Permission-Scoped Knowledge & Data Engine
VaultRAG: Permission-scoped enterprise search and automated data hygiene.
Deduplicates messy CRM records and answers operational questions across internal SOPs, contracts, and databases with role-level access controls and exact page citations.
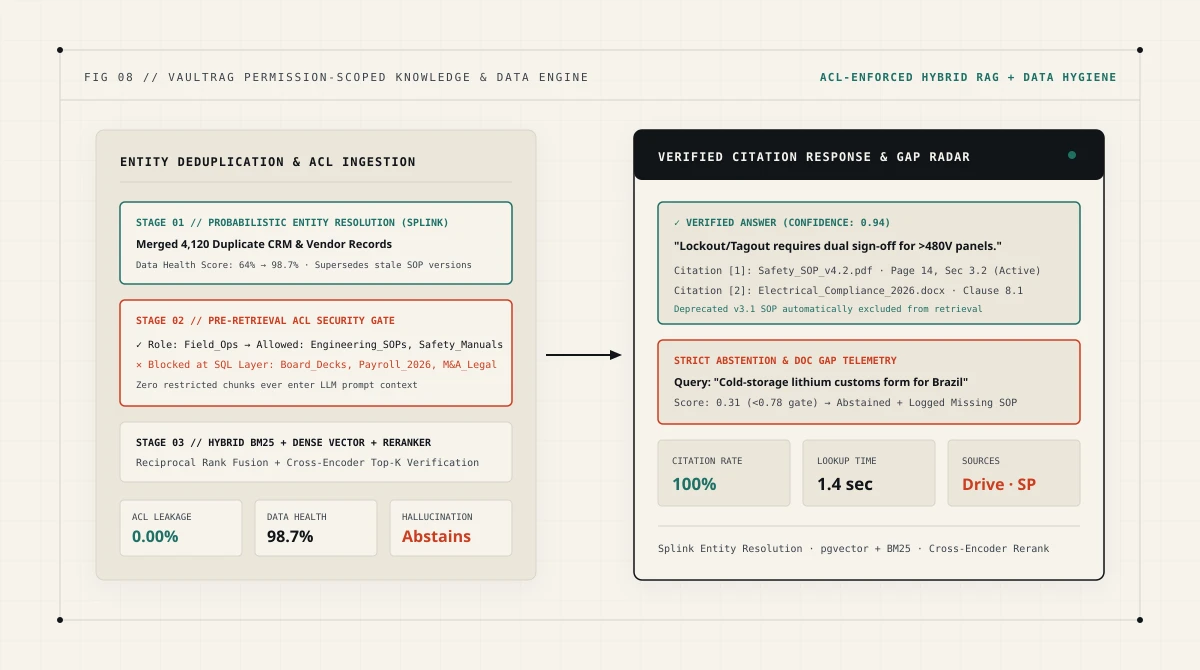
System Architecture Schematic
The Business Pain Point & Operational Requirements
Why off-the-shelf software breaks under this workflow.
Every scaling company accumulates two compounding data liabilities: dirty structured records (duplicate customer profiles, conflicting vendor spreadsheets, inconsistent SKU attributes) and fragmented unstructured knowledge (SOPs, client contracts, engineering specs, and HR policies buried across Google Drive, SharePoint, Notion, and Slack).
Standard "chat with your docs" AI prototypes fail immediately in production for two reasons: they ingest duplicate or outdated v1 documents alongside current policies—causing the AI to cite deprecated rules—and they ignore file-level permissions, risking a junior employee or contractor retrieving confidential executive, legal, or payroll figures.
What the operation required
- 01Audit, deduplicate, and standardize messy CRM, vendor, and catalog records before they pollute reporting or AI retrieval.
- 02Unify search and question-answering across PDFs, Word docs, spreadsheets, wikis, and relational databases with sub-2-second latency.
- 03Enforce strict, zero-leakage Access Control Lists (ACLs) so users only ever retrieve answers from documents their identity role is authorized to read.
- 04Guarantee every answer includes clickable document/page citations, refuses to guess when confidence is low, and logs missing-documentation gaps for ops leaders.
In-Depth Features & Functional Modules
What the system does in production
Automated data hygiene & probabilistic entity deduplication
Scans relational tables and spreadsheets to score data health, normalize phone/address/tax schemas, and merge duplicate customer or supplier entities using probabilistic record linkage (`Splink`) with human-in-the-loop review for borderline matches.
Document version control & canonical SOP indexing
Detects near-duplicate and superseded policy drafts across Drive and SharePoint, automatically archiving stale versions so retrieval only indexes the active, approved SOP or contract.
Pre-retrieval ACL enforcement & hybrid search
Mirrors source identity groups (Google Workspace, Entra ID / Active Directory, RBAC roles) onto every indexed chunk—filtering at the database layer before running hybrid BM25 keyword + dense vector search and cross-encoder reranking.
Inline page citations, strict abstention & gap telemetry
Every generated response links directly to the exact document, page number, and highlighted passage. When retrieval confidence falls below the verification threshold, the system abstains and logs the unanswered question to an Operations Knowledge Gap dashboard.
Technical Architecture
Four-stage production pipeline
Data Hygiene & Entity Resolution Stage
Runs schema validation, deterministic normalization, and Splink Fellegi-Sunter probabilistic deduplication across structured records and document metadata.
ACL-Mirrored Connector & Chunking Pipeline
Incremental connectors ingest Drive, SharePoint, Notion, and SQL sources, preserving layout hierarchy and attaching explicit role/group ACL bitmasks to every chunk.
Security-Trimmed Hybrid Retrieval + Reranker
Applies mandatory SQL `WHERE acl && user_roles` pre-filtering prior to Reciprocal Rank Fusion (BM25 + pgvector) and cross-encoder top-K reranking.
Grounded Synthesis & Abstention Gate
Generates answers constrained strictly to retrieved passages, verifies citation alignment, and routes low-confidence queries to the Knowledge Gap telemetry log.
Engineering Complexity & Stack
Hard technical problems solved under the hood
Zero-leakage security trimming before vector similarity
Never relied on post-retrieval filtering or prompt instructions for security; engineered composite PostgreSQL indexes combining GIN role arrays with HNSW vector graphs so restricted chunks are excluded before similarity scoring.
Preventing "garbage-in" hallucinations from stale & duplicate files
Built an ingestion pre-flight pipeline that resolves duplicate entities and flags conflicting document versions (such as `Refund_Policy_2024.pdf` vs `Refund_Policy_2026_FINAL.pdf`) before embeddings are committed.
Calibrated abstention over confident fabrication
Implemented a two-threshold reranker gate: when the top cross-encoder relevance score falls below `0.78`, the engine refuses to speculate, states exactly what policy is missing, and alerts the documentation owner.
Architectural Takeaways
Principles we carry into every custom deployment
Principle 01
Enterprise RAG is a data hygiene and permissions engineering problem first; cleaning duplicate records and deprecated files improves answer accuracy more than swapping foundation models.
Principle 02
An internal assistant that knows when to say "That procedure is not documented in your authorized SOPs" is infinitely more valuable than one that guesses.
Explore More Case Studies
Other systems we have architected
Okebase
Multi-Entity ERP & Operations LedgerUnifies inventory, purchasing, approvals, and consolidated accounting across subsidiaries with database-enforced tenant isolation and sub-50ms ledger queries.
VoxFlow
Autonomous Voice & Lead Dispatch EngineAnswers every inbound call on the first ring, dials new web leads within 45 seconds, locks live calendar slots, and syncs the CRM.
AdVantage
Omnichannel AI Sales & Campaign EngineUnifies WhatsApp, Instagram, and Messenger with a catalog-grounded AI sales representative and closed-loop Meta campaign automation.
Opsera
Slack-Native Company Operations OSRuns daily standups, leave approvals, RBAC task tracking, and AI thread-to-task structuring in Slack, synced with an executive web cockpit.
SyncDaily
Personalized AI Intelligence PlatformIngests and deduplicates global AI research, model releases, and market moves into tailored impact briefings for leaders, engineers, and students.
LedgerFlow
Autonomous AP & 3-Way Match PipelineExtracts multi-page vendor PDFs with deterministic math checks, reconciles lines against purchase orders and receipts, and posts clean vouchers to the ERP.
RunwayIQ
13-Week Treasury, BI & Demand ForecasterConsolidates accounting, commerce, and warehouse data to project rolling 13-week cash runway, flag inventory stockouts early, and simulate financial scenarios.
Dealing with a similar operational bottleneck?
We architect, customize, and deploy systems like this tailored to your workflow and contract structure—or start with a free 2–4 page written systems review.